Canonical HTML: https://autolyap.github.io/examples/davis_yin_three_operator/
Documentation version: 0.2.1
# The Davis–Yin three-operator splitting method
## Problem setup
Consider the composite minimization problem
\[\minimize_{x \in \calH} f_1(x) + f_2(x) + f_3(x),\]
where:
- \(f_1 : \calH \to \reals\) is convex and \(L_1\)-smooth, with \(L_1>0\),
- \(f_2 : \calH \to \reals\) is \(\mu_2\)-strongly convex and \(L_2\)-smooth,
with \(0<\mu_2\le L_2\),
- \(f_3 : \calH \to \reals \cup \set{\pm\infty}\) is proper, convex, and lower semicontinuous.
Equivalently, we solve
\[\text{find } x \in \calH \text{ such that } 0 \in \partial f_1(x) + \nabla f_2(x) + \partial f_3(x).\]
For an initial point \(x^0 \in \calH\), step size
\(\gamma \in \reals_{++}\), and relaxation
\(\lambda \in \reals\), the Davis–Yin method
[[DY17](https://autolyap.github.io/examples/davis_yin_three_operator/#id64 "Damek Davis and Wotao Yin. A three-operator splitting scheme and its optimization applications. Set-Valued and Variational Analysis, 25(4):829–858, June 2017. doi:10.1007/s11228-017-0421-z.")] is
\[\begin{split}(\forall k \in \naturals)\quad
\left[
\begin{aligned}
v^k &= \prox_{\gamma f_1}(x^k), \\
w^k &= \prox_{\gamma f_3}\!\left(2v^k - x^k - \gamma \nabla f_2(v^k)\right), \\
x^{k+1} &= x^k + \lambda (w^k - v^k).
\end{aligned}
\right.\end{split}\]
In this example, we fix
\(\mu_2 = 1\), \(L_2 = 2\), \(\lambda = 1\),
\(\gamma = 1/L_2\), sweep \(L_1 \in (0, 40]\), and search for the
smallest contraction factor \(\rho\in[0,1)\) provable using AutoLyap such that
\[\|v^k - x^\star\|^2 \in \mathcal{O}(\rho^k) \quad \textup{ as } \quad k\to\infty,\]
where
\[x^\star \in \Argmin_{x \in \calH} f_1(x) + f_2(x) + f_3(x).\]
## Model the problem in AutoLyap and search for the smallest rho
- \(f_1\) is modeled by
[`SmoothConvex`](https://autolyap.github.io/function_classes/#autolyap.problemclass.SmoothConvex "autolyap.problemclass.SmoothConvex").
- \(f_2\) is modeled by
[`SmoothStronglyConvex`](https://autolyap.github.io/function_classes/#autolyap.problemclass.SmoothStronglyConvex "autolyap.problemclass.SmoothStronglyConvex").
- \(f_3\) is modeled by
[`Convex`](https://autolyap.github.io/function_classes/#autolyap.problemclass.Convex "autolyap.problemclass.Convex").
- The inclusion is represented by
[`InclusionProblem`](https://autolyap.github.io/problem_class/#autolyap.problemclass.InclusionProblem "autolyap.problemclass.InclusionProblem").
- The update rule is represented by
[`DavisYin`](https://autolyap.github.io/concrete_algorithms/#autolyap.algorithms.DavisYin "autolyap.algorithms.DavisYin").
- Distance-to-solution parameters are obtained with
[`IterationIndependent.LinearConvergence.get_parameters_distance_to_solution`](https://autolyap.github.io/iteration_independent_analysis/#autolyap.IterationIndependent.LinearConvergence.get_parameters_distance_to_solution "autolyap.IterationIndependent.LinearConvergence.get_parameters_distance_to_solution").
- The contraction factor is searched with
[`IterationIndependent.LinearConvergence.bisection_search_rho`](https://autolyap.github.io/iteration_independent_analysis/#autolyap.IterationIndependent.LinearConvergence.bisection_search_rho "autolyap.IterationIndependent.LinearConvergence.bisection_search_rho").
## Run the iteration-independent analysis
This example uses the MOSEK Fusion backend (`backend="mosek_fusion"`).
Install the optional MOSEK dependency first:
```bash
pip install "autolyap[mosek]"
```
```python
from autolyap import IterationIndependent, SolverOptions
from autolyap.algorithms import DavisYin
from autolyap.problemclass import Convex, InclusionProblem, SmoothConvex, SmoothStronglyConvex
L1 = 1.0
mu2 = 1.0
L2 = 2.0
lambda_value = 1.0
gamma = 1.0 / L2
problem = InclusionProblem(
[
SmoothConvex(L=L1), # f1
SmoothStronglyConvex(mu=mu2, L=L2), # f2
Convex(), # f3
]
)
algorithm = DavisYin(gamma=gamma, lambda_value=lambda_value)
solver_options = SolverOptions(backend="mosek_fusion")
# License-free option:
# solver_options = SolverOptions(backend="cvxpy", cvxpy_solver="CLARABEL")
P, p, T, t = IterationIndependent.LinearConvergence.get_parameters_distance_to_solution(
algorithm
)
result = IterationIndependent.LinearConvergence.bisection_search_rho(
problem,
algorithm,
P,
T,
p=p,
t=t,
S_equals_T=True,
s_equals_t=True,
remove_C3=True,
solver_options=solver_options,
)
if result["status"] != "feasible":
raise RuntimeError("No feasible Lyapunov certificate in the requested rho interval.")
rho_autolyap = result["rho"]
rho_davis_yin = 1.0 - mu2 / (L2 * (1.0 + L1 / L2) ** 2)
rho_pedregosa_gidel = 1.0 - min(mu2 / L2, 1.0 / (1.0 + L1 / L2))
print(f"rho (AutoLyap): {rho_autolyap:.8f}")
print(f"rho (Davis-Yin bound): {rho_davis_yin:.8f}")
print(f"rho (Pedregosa-Gidel): {rho_pedregosa_gidel:.8f}")
```
What to inspect in `result`:
- `result["status"]`: `feasible`, `infeasible`, or `not_solved`.
- `result["solve_status"]`: raw backend status.
- `result["rho"]`: certified contraction factor when feasible.
- `result["certificate"]`: Lyapunov certificate matrices/scalars.
For \(\lambda=1\) and \(\gamma=1/L_2\), we compare against:
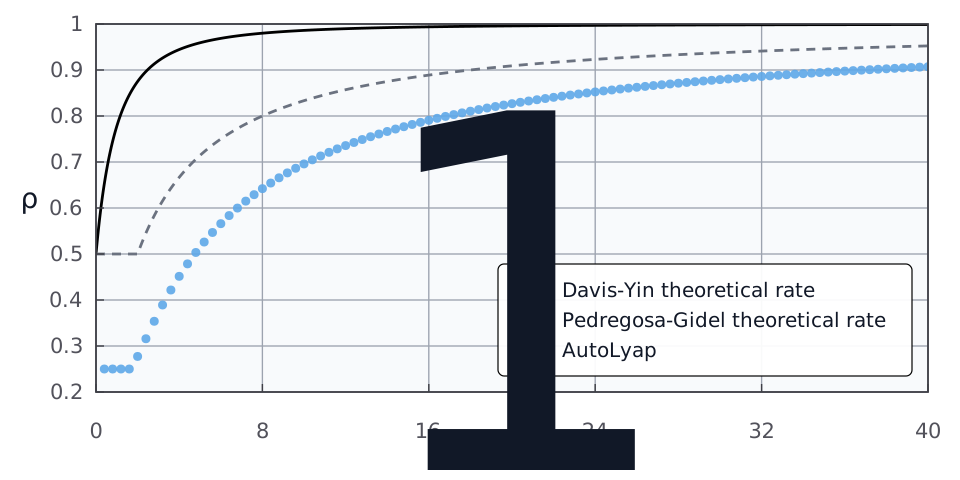
\[\rho_{\text{DY}} = 1 - \frac{\mu_2}{L_2\left(1+L_1/L_2\right)^2}.\]
This is the specialization of
[[DY15](https://autolyap.github.io/examples/davis_yin_three_operator/#id63 "Damek Davis and Wotao Yin. A three-operator splitting scheme and its optimization applications. arXiv preprint arXiv:1504.01032, April 2015. arXiv:1504.01032v1."), Theorem D.6, case 6] under:
- case-6 assumptions (`B` Lipschitz and `C` strongly monotone),
- parameter choice \(\lambda=1\),
- limiting choices \(\varepsilon \to 1\) and \(\eta \to 1/2\),
- identifications \(L_B=L_1\), \(\mu_C=\mu_2\), and
\(\gamma=1/L_2\).
We also compare against:
\[\rho_{\text{PG}} = 1 - \min\!\left\{\frac{\mu_2}{L_2},\;\frac{1}{1+L_1/L_2}\right\}.\]
This matches the non-adaptive TOS specialization of
[[PG18](https://autolyap.github.io/examples/davis_yin_three_operator/#id159 "Fabian Pedregosa and Gauthier Gidel. Adaptive three operator splitting. In Jennifer Dy and Andreas Krause, editors, Proceedings of the 35th International Conference on Machine Learning, volume 80 of Proceedings of Machine Learning Research, 4085–4094. PMLR, 10–15 Jul 2018."), Eq. (16), Theorem 3]:
- define \(\rho=\mu_2\min\{\gamma,\tau/L_2\}\) and
\(\sigma=1/(1+\gamma L_1)\),
- use \(\tau=1\) and \(\gamma=1/L_2\),
- then \(\rho=\mu_2/L_2\) and \(\sigma=1/(1+L_1/L_2)\),
which yields \(1-\min\{\rho,\sigma\}\).
Sweeping over 100 values of \(L_1\) on \((0, 40]\) gives the plot
below, with the two theoretical expressions as lines and AutoLyap certificates
as blue dots.
[](https://autolyap.github.io/_images/davis_yin_three_operator_rho_vs_l1.svg)
## References
[[DY15](https://autolyap.github.io/examples/davis_yin_three_operator/#id2)]
Damek Davis and Wotao Yin. A three-operator splitting scheme and its optimization applications. *arXiv preprint arXiv:1504.01032*, April 2015. [arXiv:1504.01032v1](https://arxiv.org/abs/1504.01032v1).
[[DY17](https://autolyap.github.io/examples/davis_yin_three_operator/#id1)]
Damek Davis and Wotao Yin. A three-operator splitting scheme and its optimization applications. *Set-Valued and Variational Analysis*, 25(4):829–858, June 2017. [doi:10.1007/s11228-017-0421-z](https://doi.org/10.1007/s11228-017-0421-z).
[[PG18](https://autolyap.github.io/examples/davis_yin_three_operator/#id3)]
Fabian Pedregosa and Gauthier Gidel. Adaptive three operator splitting. In Jennifer Dy and Andreas Krause, editors, *Proceedings of the 35th International Conference on Machine Learning*, volume 80 of Proceedings of Machine Learning Research, 4085–4094. PMLR, 10–15 Jul 2018.
TeX macro definitions used in this page:
```latex
\newcommand{\Argmin}{\operatorname*{Argmin}}
\newcommand{\calH}{\mathcal{H}}
\newcommand{\minimize}{\operatorname*{minimize}}
\newcommand{\naturals}{\mathbb{N}_{0}}
\newcommand{\prox}{{\rm{prox}}}
\newcommand{\reals}{\mathbb{R}}
\newcommand{\set}[1]{\mathord{\left.\{ #1 \} \right. }}
```